
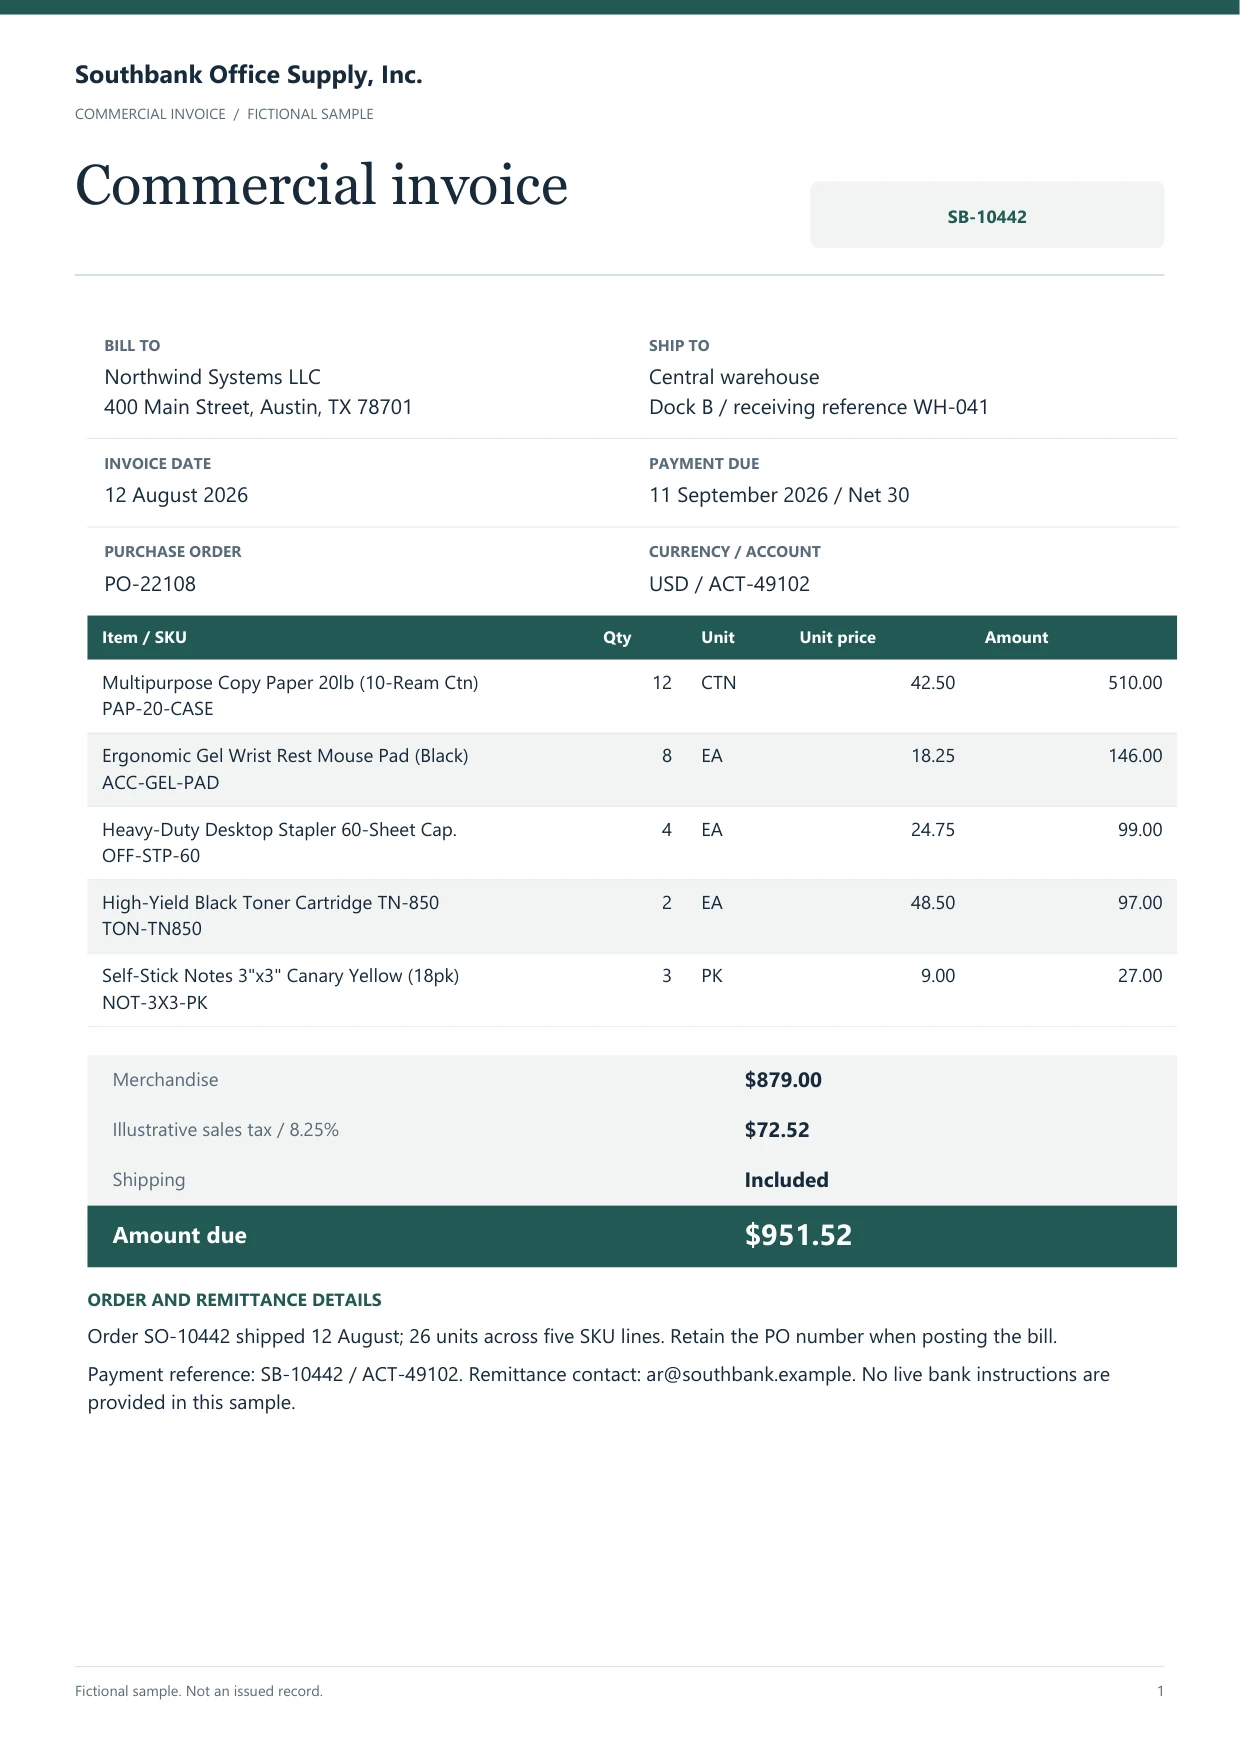
Office supply invoice · 1 page
Choose an OCR workflow by document type. Check which fields and rows you need from a scan or image.
Traditional OCR turns pixels into characters. That is enough when you need searchable text. OCR data extraction has a harder job: it must keep a supplier name attached to its label, place an amount in the right column and carry a table row across the page without inventing a new record.
Dynamite Docs combines document OCR with structure and review. Use the guides below to choose the right path for scanned PDFs, invoices, receipts, bank statements, photos, tables and handwriting, then test the result on your own files.
 Dynamite Docs
PDF + reviewed results
Office supply invoice · 1 page
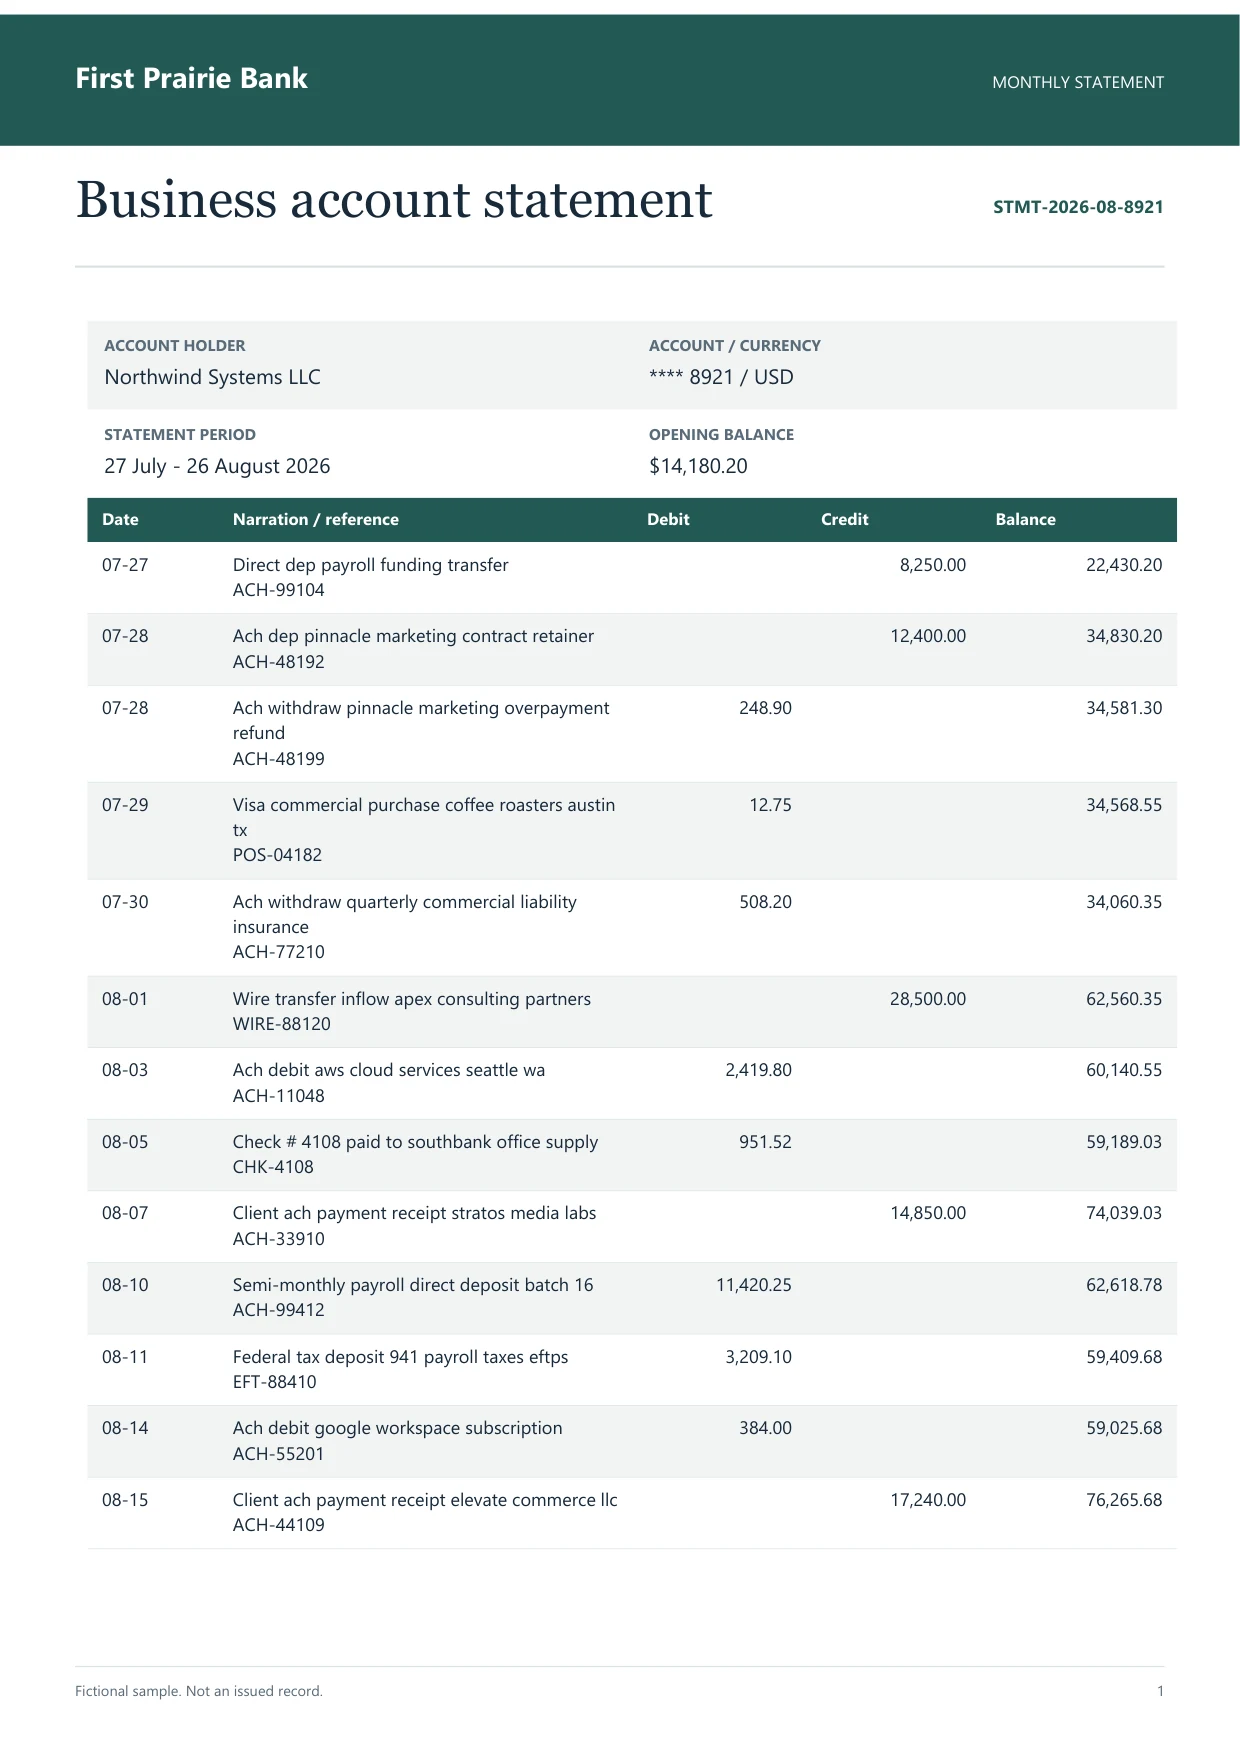
Bank statement · 2 pages
Searchable text, a spreadsheet and an API payload are different products. An archive needs readable text with page references. A finance workflow needs named fields, typed amounts, repeating rows and rules that stop a bad value before export. The destination tells you whether plain OCR is enough or whether you also need layout analysis and review.
Start with the file itself. A digital PDF may already contain reliable text even when copy and paste looks messy. An image-only PDF needs recognition, while a mixed packet may need a different path on each page. Running every file through visual OCR can replace clean embedded text with a less certain reading.
Keep the schema as small as the job allows. An invoice needs supplier, document, tax, line-item and total fields. A bank statement needs transaction rows and balance checks. Capturing every visible word creates more noise for the reviewer and the next system.
One document-level accuracy score can hide the error that matters. Test whether table values stayed in the right row and column. Recalculate invoice totals. Reconcile statement balances. Compare every character in identifiers and keep leading zeroes.
Build a test set with clean originals, scans, phone photos, unfamiliar layouts and the worst files the team receives. Record field corrections separately from structural failures. That evidence helps you decide which files can pass, which need review and which need a better source image.
Confidence and validation answer different questions. Confidence helps set the review order. Business rules catch values that look plausible on their own but conflict with totals, balances or document identifiers.
Dynamite DocsDynamite DocsProduces a text layer or reading-order transcript. It works for search and copying, but it may flatten tables or separate labels from their values.
Uses page position and layout to keep headings, key-value pairs, paragraphs and page regions connected.
Returns named fields, rows and typed values for Excel, JSON, an accounting system or an API.
Document guides
 PDF OCRExtract scanned PDF text, fields, and tables with AI OCR in Dynamite Docs. Compare uncertain values with the source before exporting reviewed data.
 Invoice OCRExtract invoice totals, taxes, and line items with AI OCR in Dynamite Docs. Review supplier fields and table rows beside the source before export.
 Receipt OCRRead receipt scans and photos with AI OCR in Dynamite Docs. Check merchant names, dates, tax, tips, and faded totals against the source before export.
 Bank statement OCRExtract bank statement transactions with AI OCR in Dynamite Docs. Review dates, debits, credits, and balances before preparing reconciliation rows.Image OCRExtract structured fields and tables from images with AI in Dynamite Docs. Review document photos, screenshots, and scans beside the source before export.Scanned document OCRExtract fields and tables from low-resolution or skewed scans with AI in Dynamite Docs. Check uncertain values and page order before exporting.
 Table OCRExtract borderless and multi-page tables with AI OCR in Dynamite Docs. Review columns, wrapped text, and continued rows before spreadsheet export.Handwriting OCRExtract handwritten form fields, notes, and totals with AI OCR in Dynamite Docs. Review unclear characters beside the source before exporting values.
Check whether the file already contains reliable text. Digital PDFs may be parsed directly. Scans and photos need visual recognition.
Character recognition reads the page. The document model groups that text into fields, paragraphs, tables and repeating rows.
A useful schema keeps dates, amounts, identifiers and line items separate instead of returning one long text block.
Compare uncertain text, totals, row boundaries and ambiguous characters with the source before export or automation.
Free OCR tools
Upload one supported file and review the extraction before creating an account. Pick the tool that matches the document and output.
OCR recognizes characters in an image. AI OCR also uses layout and document context, which lets it return named fields and tables instead of only a transcript.
Yes. Each scanned page is treated as an image. Results depend on resolution, rotation, compression, contrast, handwriting, and whether important text is hidden by stamps or folds.
That depends on the job. Search needs text and page coordinates. Automation usually needs named fields, typed values, repeating rows, page references, confidence, and a way to inspect the source.
Some clean, repeated layouts can reach straight-through processing after testing. Financial totals, account numbers, handwriting, and unfamiliar layouts should start with human review and explicit validation rules.
Connected Accounting & Document Automation
Use the REST API for structured extraction, or open the workspace to test a file with review beside the source.
Can we save optional cookies?
Essential cookies keep you signed in. With your permission, optional analytics cookies and masked session replays help us understand usage and diagnose errors. Privacy policy. Change your choice anytime in Cookie settings.