Sections08
Reading time8 min
EvidenceProduct guide

Answer in 30 seconds

Pull fields, tables and line items out of a PDF, check them against the page and download data that is ready for the next step.

Copy and paste works until a PDF contains wrapped rows, repeated headers or pages that are only images. AI PDF data extraction handles both kinds of file. It reads the embedded text in a digital PDF and uses visual recognition when a scanned page has no usable text layer.

Dynamite Docs turns the result into named fields and rows instead of leaving you with a transcript. Open the original PDF beside the extracted table, correct doubtful cells and export the reviewed data to Excel, CSV, JSON or Google Sheets.

Try a PDF in your browser. Sign up only when you want to download or keep the result.
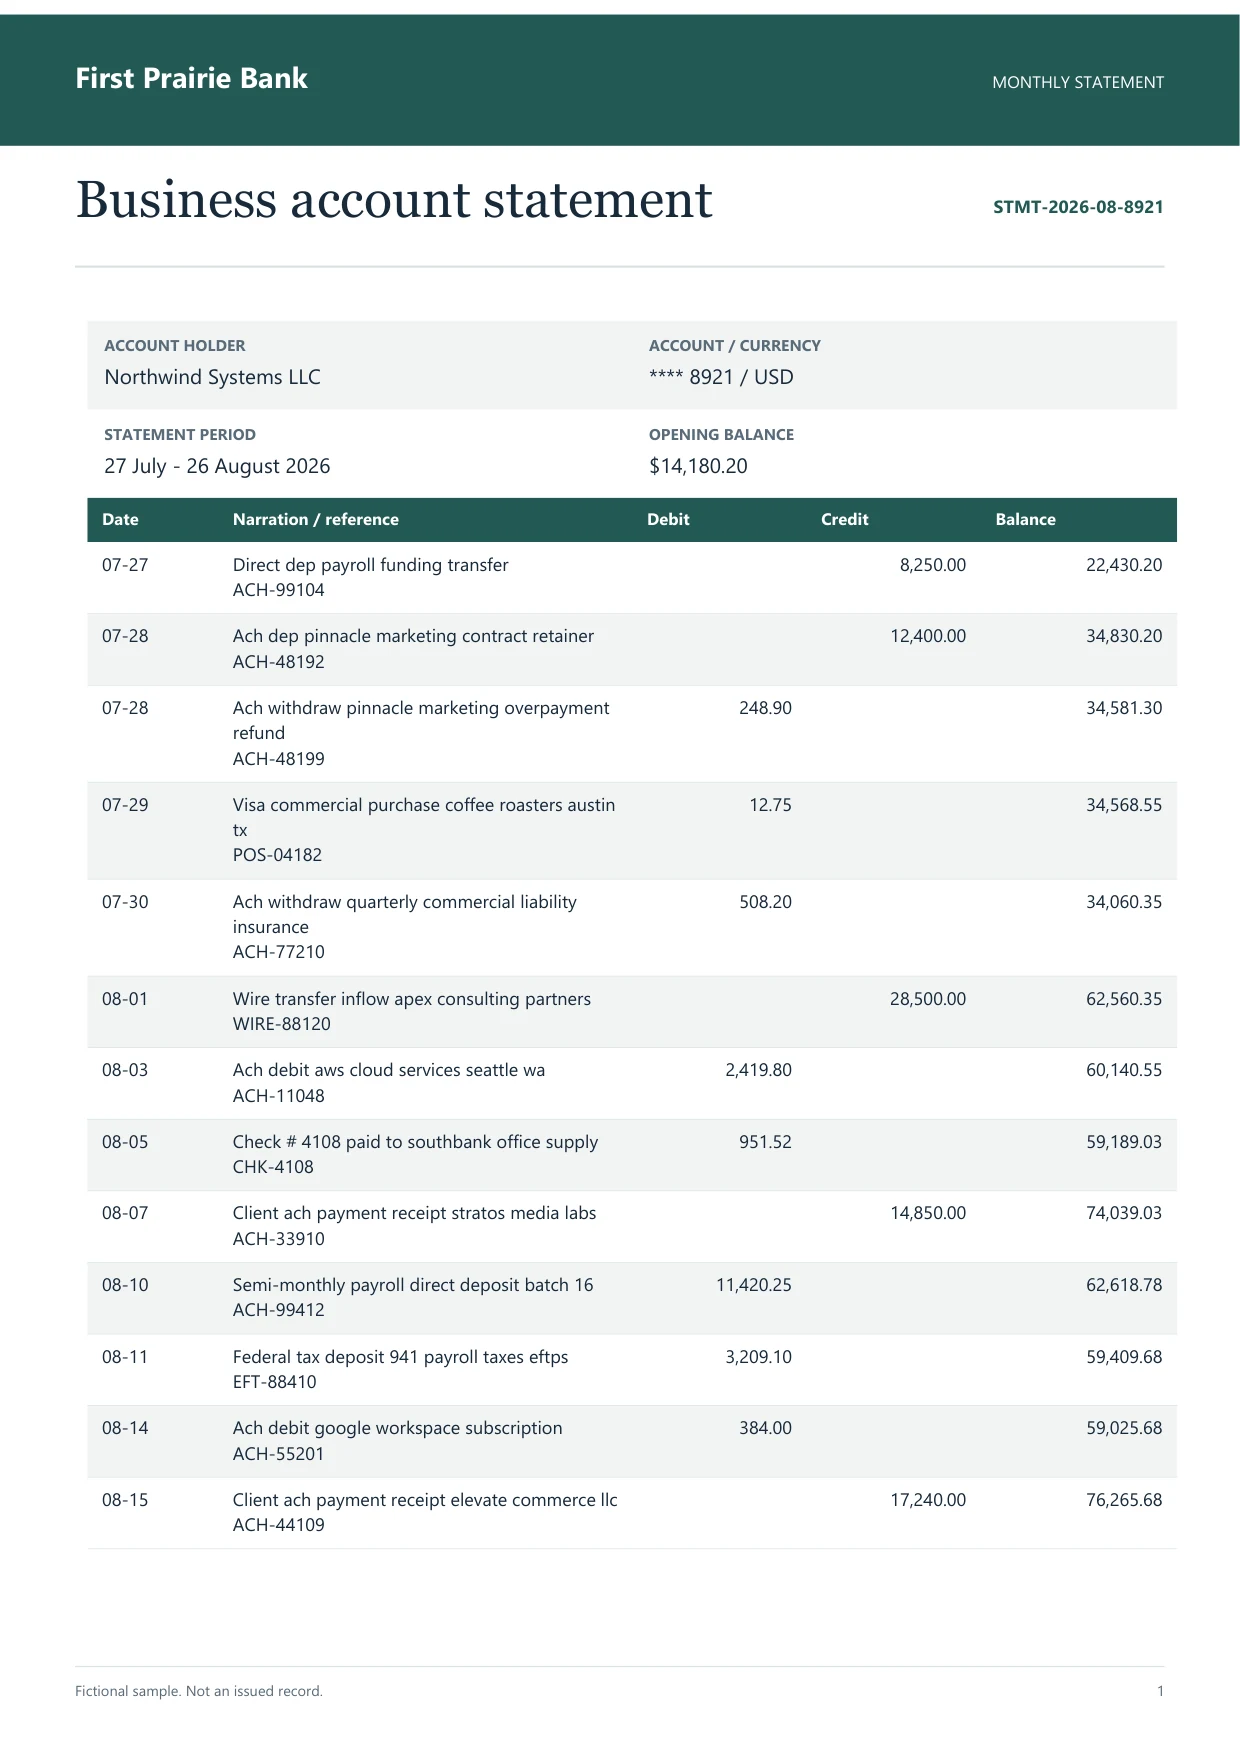
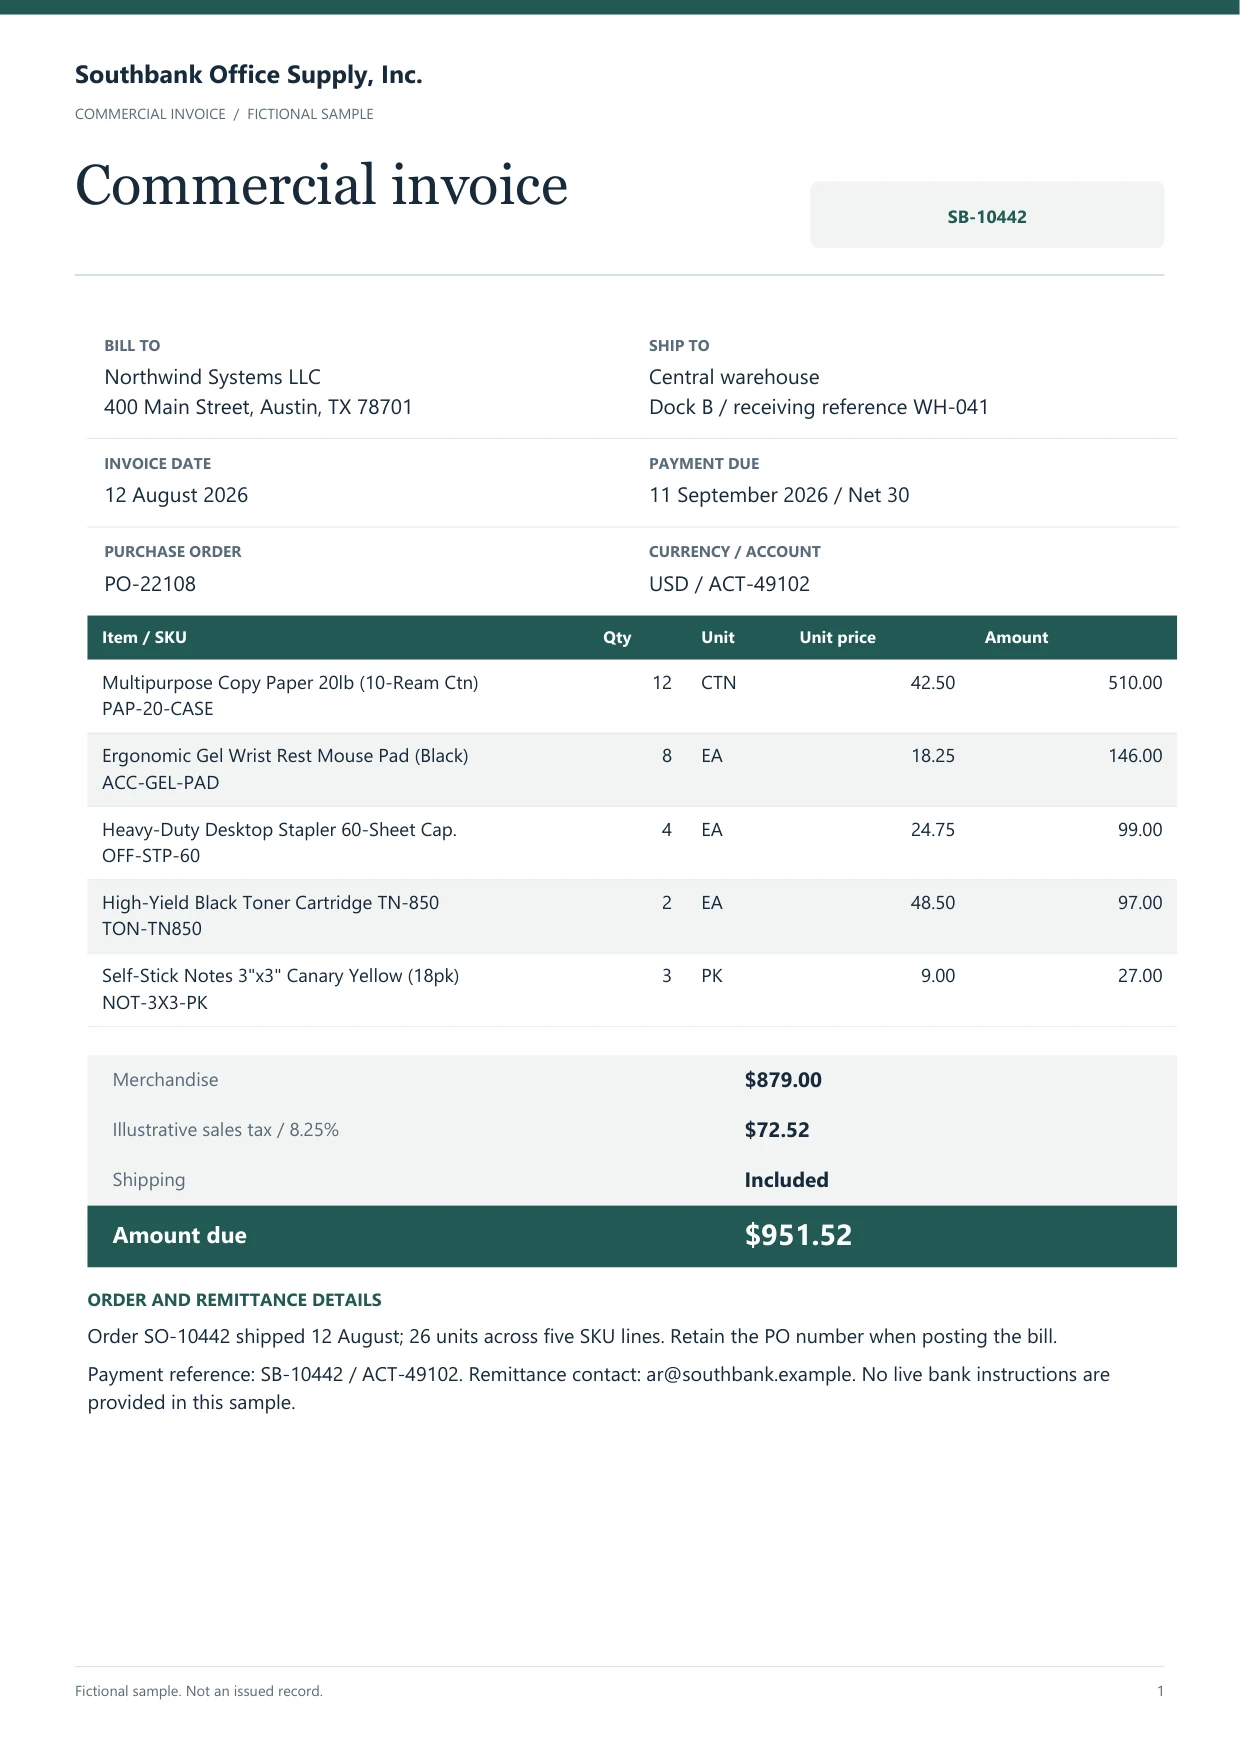
Check document extraction results with Dynamite Docs with these sample files

Input register

Start with a digital, scanned or mixed PDF using Dynamite Docs

01

Digital native PDFs

Read embedded text before using layout and model inference to organize fields and tables.

02

Scanned PDF documents

Process image-based pages with visual AI OCR to recover text, numbers, and tabular boundaries.

03

Multi-page tables

Join continuing rows across pages, then review repeated headers, wrapped records and subtotals.

04

Complex column layouts

Distinguish multi-column text blocks from tables and flag column boundaries for review.

Extraction schema

Preserve the structure that makes the PDF useful

Keep document details, repeating rows and source references separate so the output is easier to review and import.

Dynamite Docs logoDynamite Docs
Inside the output
Source document: Read the PDF tablesDocument metadata: Report name, account reference, statement period, issue date. Tabular line items: Item code, description, quantity, unit price, total amount. Running balances: Opening balance, debits, credits, closing balance. Illustrative example, not extracted customer data.Read the PDF tablesfx Values from your documentAOutput formatBStructureCUseful when12345Excel (.xlsx)Structured worksheets…Financial modeling,…CSVPlain comma-delimited…Direct database import,…JSONColumn definitions, row…Web application…Document fields / RowsEditable cells,…
Document metadata
Report name, account reference, statement period, issue date
Tabular line items
Item code, description, quantity, unit price, total amount
Running balances
Opening balance, debits, credits, closing balance
Keep each PDF table with its source. Illustrative example.
Document metadataReport name, account reference, statement period, issue date
Tabular line itemsItem code, description, quantity, unit price, total amount
Running balancesOpening balance, debits, credits, closing balance
Tax and deductionsTaxable amounts, tax rates, withholding, gross totals
Confidence metricsReliability scores calculated for every extracted table cell
Source coordinatesPage and region references when the extraction backend returns coordinates

Procedure

From file to reviewed result

Dynamite Docs logoDynamite Docs
The handoff
Source document: Read the PDF tablesUpload the original PDF. Read text and page layout. Review cells beside the page. Export the reviewed result. Illustrative example, not extracted customer data.FROM SOURCE FILE TO A RESULT YOU CAN USESourcedocumentReview workspaceRead thePDF tables1Upload theoriginal PDF2Read text andpage layout3Review cellsbeside the page
  1. 01Upload the original PDF
  2. 02Read text and page layout
  3. 03Review cells beside the page
  4. 04Export the reviewed result
Keep each PDF table with its source. Illustrative example.
  1. 01

    Upload the original PDF using Dynamite Docs

    Choose a digital, scanned or mixed PDF in the browser. Stored files can also enter a batch through the REST API.

  2. 02

    Read text and page layout using Dynamite Docs

    The extraction path uses available text and visual context to identify fields, headers, columns and repeating rows.

  3. 03

    Review cells beside the page using Dynamite Docs

    Inspect flagged values, correct cells inline and fix column mappings before the data leaves the workspace.

  4. 04

    Export the reviewed result with Dynamite Docs

    Download an Excel workbook, CSV or JSON file, or push the table into a new Google Sheets tab.

Product evidence

Compare the extracted table with the PDF using Dynamite Docs

The PDF stays open next to the data grid. Confidence indicators point to cells worth checking, and you can correct a value in place before export.

Interactive PDF data review interface in Dynamite Docs.

Workflow Tour

8 steps

01 / Bring in files

Bring documents into one workspace.

Upload from your computer or choose files from Google Drive. Connected Dropbox and Slack workflows can bring in files too.

  • Google Drive logoGoogle Drive
  • Dropbox logoDropbox
  • Slack logoSlack
  • Local upload
Workspace preview01 / 08
Start with Import, then choose where your file comes from.
1 of 8
Worked Example: Document Input & Extracted Rows

Pick the format that fits the handoff

Use a workbook for review, CSV for a flat import, JSON for software or Google Sheets for a shared working table.

Extract PDF Data with AI for Accounting | Dynamite Docs: image OCR table extractionRead tables from an old scanned invoice without a template.
Extract PDF Data with AI for Accounting | Dynamite Docs: OCR source view controlsSwitch views when an image needs closer OCR review.
Extract PDF Data with AI for Accounting | Dynamite Docs: OCR text correctionCorrect OCR text while the original invoice stays visible.
Extract PDF Data with AI for Accounting | Dynamite Docs: reviewed OCR line itemsCorrect image-derived line items before using the result.
Output formatStructureUseful when
Excel (.xlsx)Structured worksheets with preserved data types and headersFinancial modeling, reconciliation, and audit review
CSVPlain comma-delimited rows with UTF-8 encodingDirect database import, business intelligence, and data analysis
JSONColumn definitions, row arrays, metadata and document typeWeb application backends, cloud functions, and ETL pipelines
Google SheetsReviewed data pushed into dedicated worksheet tabsTeam collaboration, client reporting, and shared dashboards

Review gate

Check the errors a tidy export can hide

Common Failure States & Troubleshooting

Password protection, damaged files, heavy skew and low resolution can block or weaken extraction. Fix the source before a large batch.

Confidence

Confidence indicators call attention to ambiguous characters such as 0 and O or 1 and l. They prioritize review but do not prove a value is correct.

Accuracy

Native digital text avoids OCR noise, but wrapped text cells and multi-line item descriptions require layout-aware parsing.

Failure state

Password protection, damaged files, heavy skew and low resolution can block or weaken extraction. Fix the source before a large batch.

Product boundary

PDF data extraction produces clean structured tables and key-value fields. It does not reproduce graphic design elements or decorative fonts.

Split automation from final approval

The software prepares and structures PDF data. The operator confirms the schema, locale and business-critical values.

ComponentPlatform roleOperator role
Document ingestionAutomated PDF parsing and text-layer discoveryUpload original high-fidelity PDF files
Table detectionAI identification of columns, rows, and headersConfirm column header names and alignments
Data normalizationDate standardizing and decimal number formattingVerify currency codes and locale conventions
Export & deliveryExcel, CSV, JSON and Sheets generationApprove final dataset before downstream entry

Confidentiality and data protection standards

Free and anonymous files stay in browser storage, but hosted inference still sends prepared document content to an eligible AI provider.

Pro and Ultra add provider-routing policies for no-training and data-residency requirements. Hobby, Pro, and Ultra can run model inference through the local Ollama companion.

Questions about pdf data extraction software

How do I extract data from a PDF into Excel?

Upload the PDF, review the detected fields and table columns beside the source, correct any doubtful values, then choose Excel to download an .xlsx workbook.

Can AI PDF data extraction handle scanned documents?

Yes. Scanned pages are rendered as images for a vision-capable model. Image quality, rotation, small type and complex table boundaries still affect the result.

How does the software handle multi-page tables in PDFs?

The extractor can link continuing rows and remove repeated headers for multi-page tables in PDFs. Review page boundaries, wrapped descriptions and subtotals before accepting the combined table.

Is my PDF data secure and private during extraction?

Files are encrypted in transit and stored files are encrypted at rest. Dynamite Docs does not use customer documents to train foundation models. Hosted and own-key requests are subject to the selected provider's handling terms. Review storage, provider, policy, and local-inference choices before processing sensitive files.

Can we save optional cookies?

Essential cookies keep you signed in. With your permission, optional analytics cookies and masked session replays help us understand usage and diagnose errors. Privacy policy. Change your choice anytime in Cookie settings.