

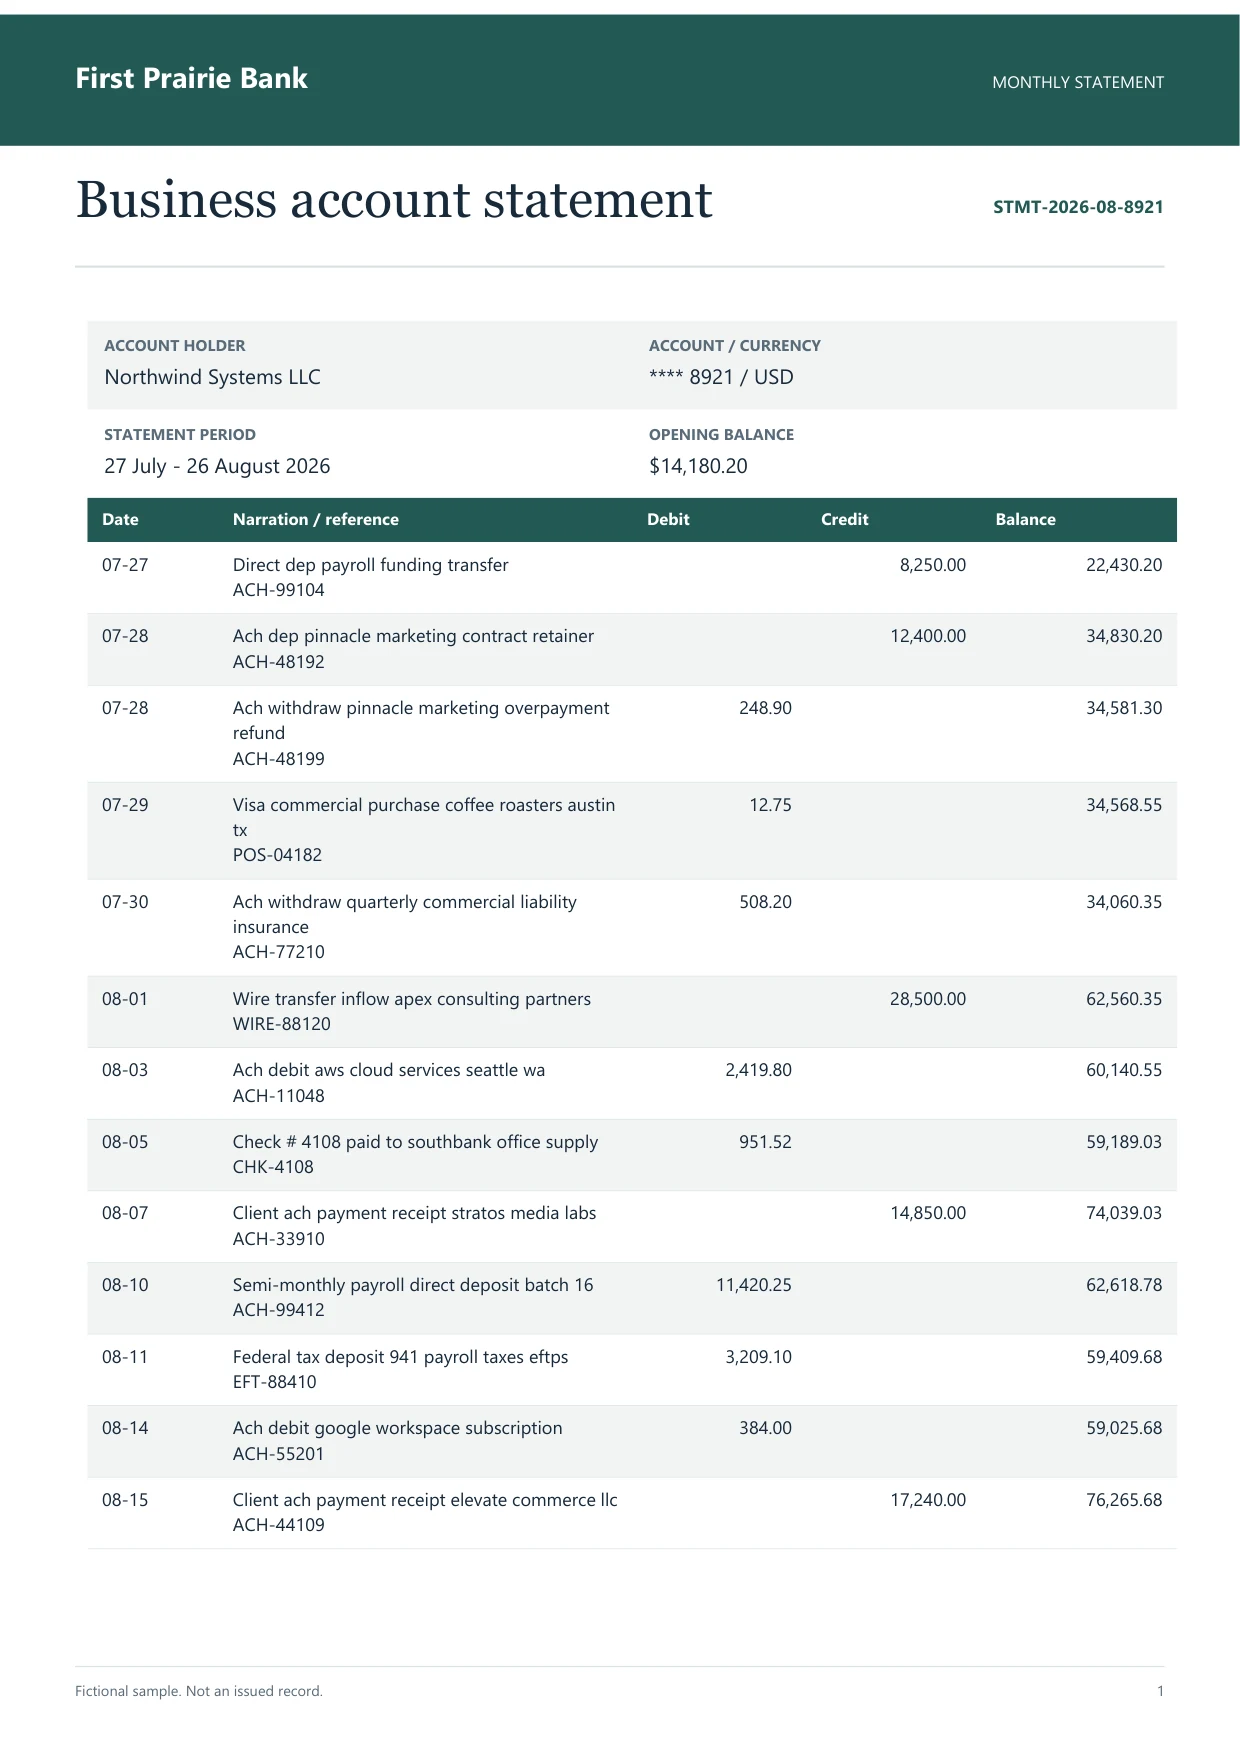
Bank statement · 2 pages
Use headers and spacing to infer columns without grid lines. Check wrapped cells and verify each amount stays in its column.
Table OCR must read the characters and rebuild the grid around them. A transcript can contain every word and still produce bad data when an amount slips into the next column or a wrapped description becomes another row.
Borderless tables, merged headings, blank cells and repeated page headers need layout context. The output should preserve row order, expose uncertain cell boundaries and keep each page available for comparison.
 Dynamite Docs
PDF + reviewed results
Bank statement · 2 pages
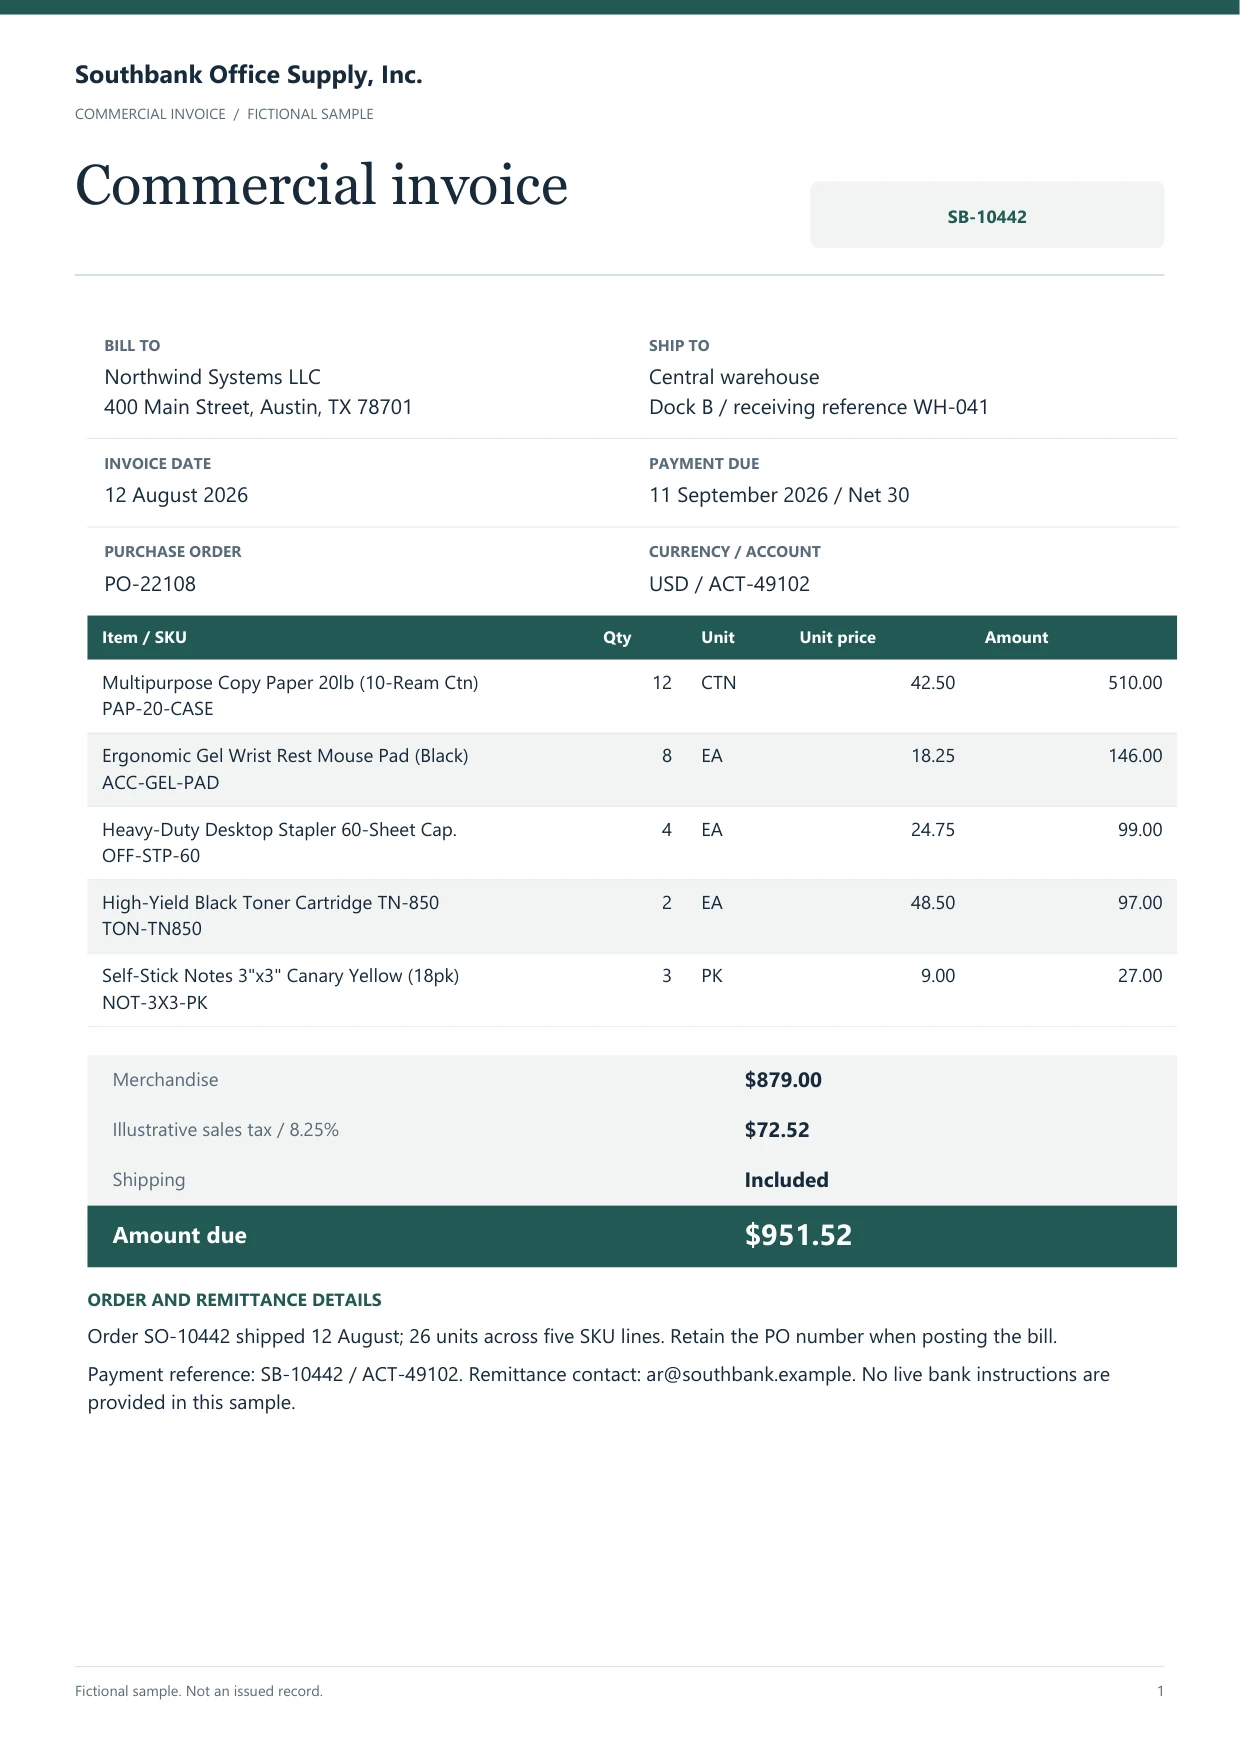
Office supply invoice · 1 page
Dynamite DocsSeparate grids and aligned value blocks from surrounding titles, notes, and page furniture.
Use borders, whitespace, alignment, and repeated value patterns to define the grid.
Keep wrapped text, blank cells, subtotals, and continuation pages attached to the right records.
Check column types, row counts, totals, and page transitions before export.
Structured output
Dynamite DocsStructural errors are dangerous because every cell may contain plausible text while the row or column assignment is incorrect.
Implementation guide
Start by marking the expected table boundaries, header levels, row count, and value types on a representative sample. Then compare the exported dataset with that reference. Character accuracy alone will not catch a debit placed under credit, a wrapped description split into two records, or a subtotal imported as an ordinary transaction.
Multi-page tables need explicit continuation rules. Repeated headers and footers should disappear from the data, but page references should remain. A row split by a page break must be joined only when the layout and values support it. Carried balances, section labels, and notes need their own treatment so they do not silently become rows.
Before opening the file in Excel, validate columns by type and relationship. Dates should parse as dates, amounts should remain numeric, and identifiers should keep leading zeroes. Compare source and output row counts, recalculate totals, and inspect blank cells. These checks find structural mistakes that a visually tidy spreadsheet can conceal.
Decide how to represent complex headers before export. A two-level header may need flattened names such as current_period_debit and prior_period_debit for CSV, while Excel can preserve a more readable multi-row heading. JSON can retain nested groups, but downstream code still needs stable keys and documented null behavior.
Keep multiple detected tables separate unless they share the same columns and business meaning. A summary grid, transaction table, and footnote schedule on one page are not one dataset. Joining them because their borders touch creates rows that look valid but cannot be reconciled.
Test the final format in the system that will consume it. Excel users may need visible review columns and frozen headers. An API client needs stable keys, data types, source coordinates, and predictable errors. The correct grid is only useful when it survives the handoff.
Return tables as arrays of typed rows plus the original header labels and source coordinates.
Support multiple tables per page and do not force unrelated grids into one schema.
Move report tables into a workbook without rebuilding rows by hand.
Recover transaction grids and preserve amounts, signs, and balances.
Convert scanned schedules into structured records with a review trail.
Free OCR tools
Upload one supported file and review the extraction before creating an account. Pick the tool that matches the document and output.
Yes. Alignment, spacing, headers, and repeated data types can reveal columns, but borderless tables usually need closer review.
Yes. [Table OCR](/blog/extract-tables-from-pdf-using-ai) can identify repeated headers and continued structures. Carried totals and page notes should be excluded with explicit validation.
Use CSV for one flat table, [Excel](/free-tools/pdf-to-excel) for several tables or manual review, and JSON when nested structure or API delivery matters.
Use the [local Ollama extraction workflow](/guides/local-ai) with a model that can return structured rows. Check borderless columns, merged headers, wrapped descriptions and repeated headings across pages. Compare row counts and totals with the original PDF before exporting Excel, CSV or JSON.
Keep reading
Extract scanned PDF text, fields, and tables with AI OCR in Dynamite Docs. Compare uncertain values with the source before exporting reviewed data.
Read guideExtract bank statement transactions with AI OCR in Dynamite Docs. Review dates, debits, credits, and balances before preparing reconciliation rows.
Read guideExtract invoice totals, taxes, and line items with AI OCR in Dynamite Docs. Review supplier fields and table rows beside the source before export.
Read guideConnected Accounting & Document Automation
Can we save optional cookies?
Essential cookies keep you signed in. With your permission, optional analytics cookies and masked session replays help us understand usage and diagnose errors. Privacy policy. Change your choice anytime in Cookie settings.