
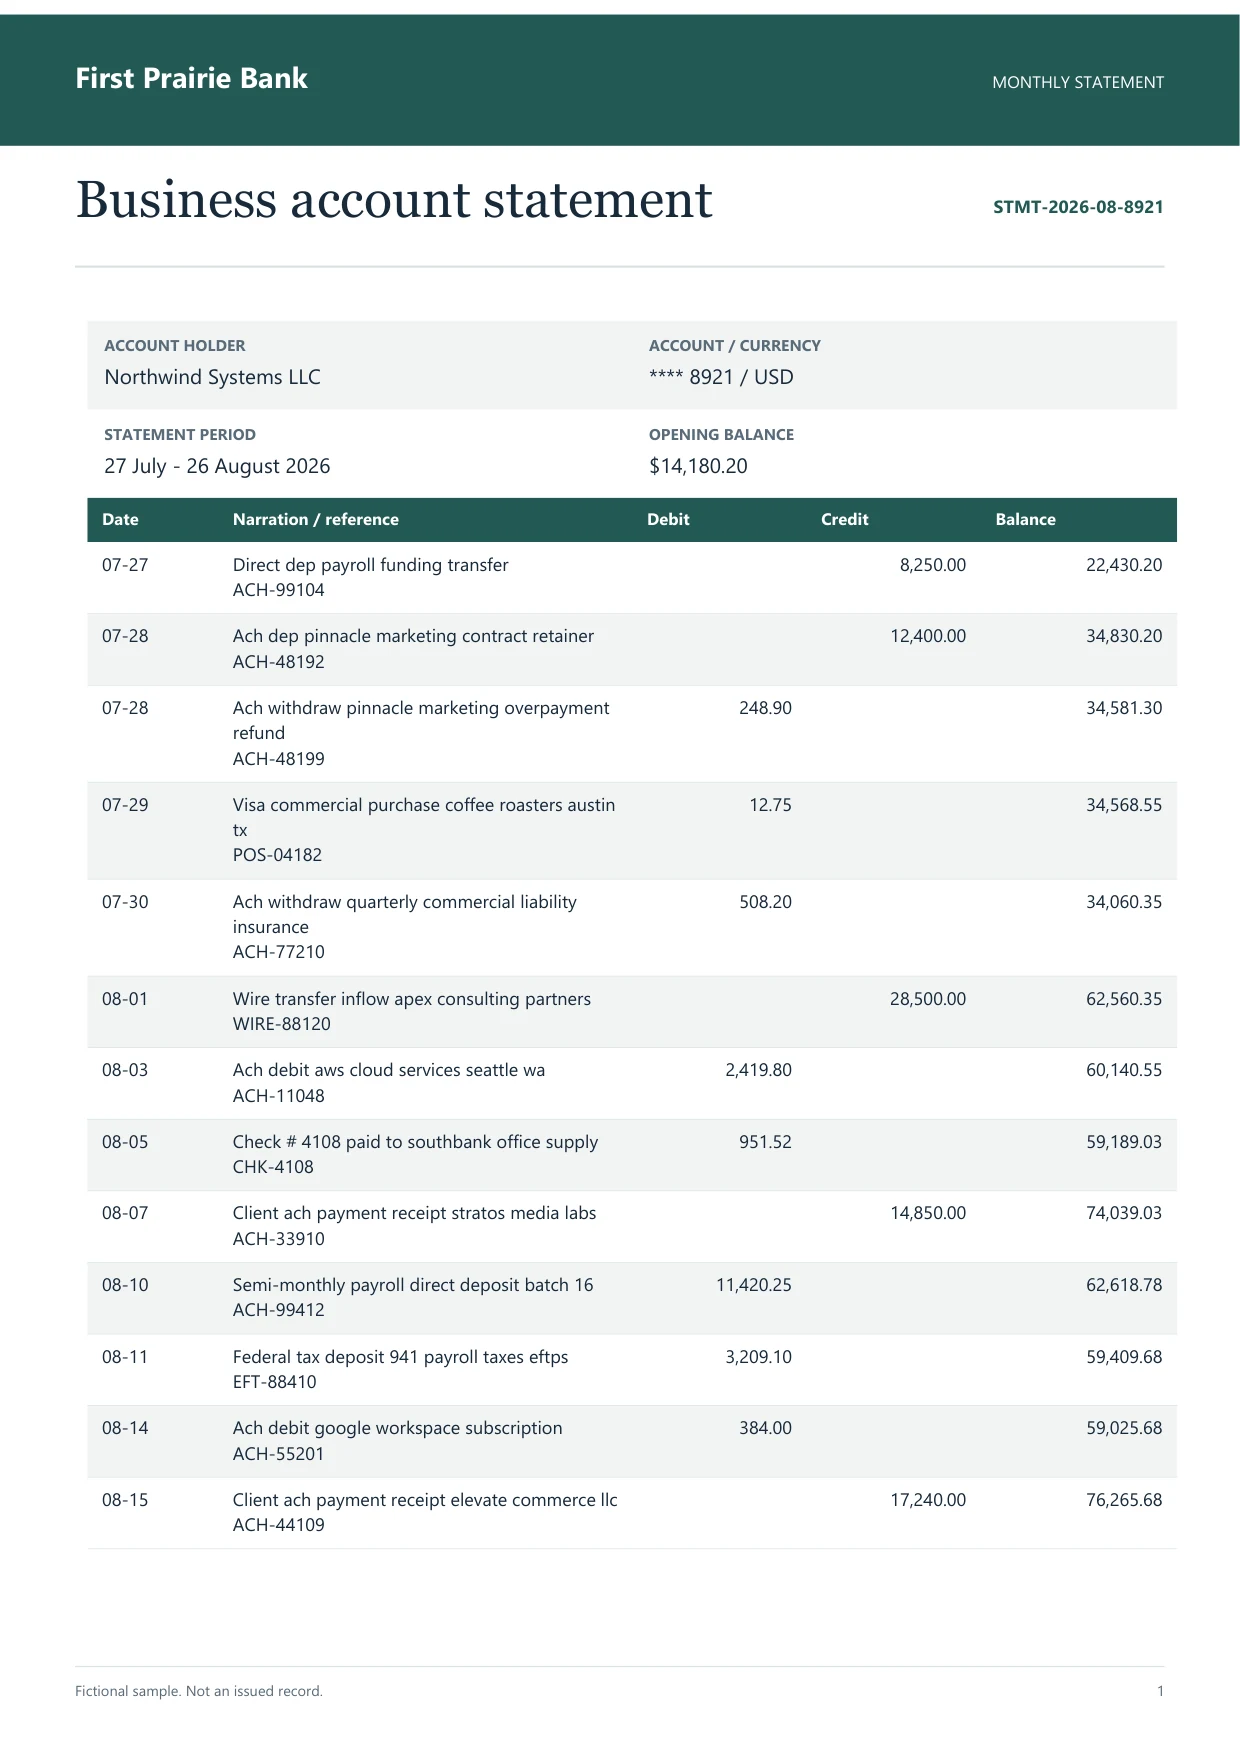
Bank statement · 2 pages
Check for selectable text first. Use OCR on image-only pages, then verify the fields and table rows against the scan.
A PDF can hold clean digital text, scanned page images or both in the same file. Check the page type first. Reliable PDF OCR uses embedded text where it can and visual recognition where it must.
Searchable text is only a starting point for PDF data extraction. Tables must keep their rows, labels must stay attached to values and repeated pages must return the same schema. Keep the page beside the output so those relationships can be checked.
 Dynamite Docs
PDF + reviewed results
Bank statement · 2 pages
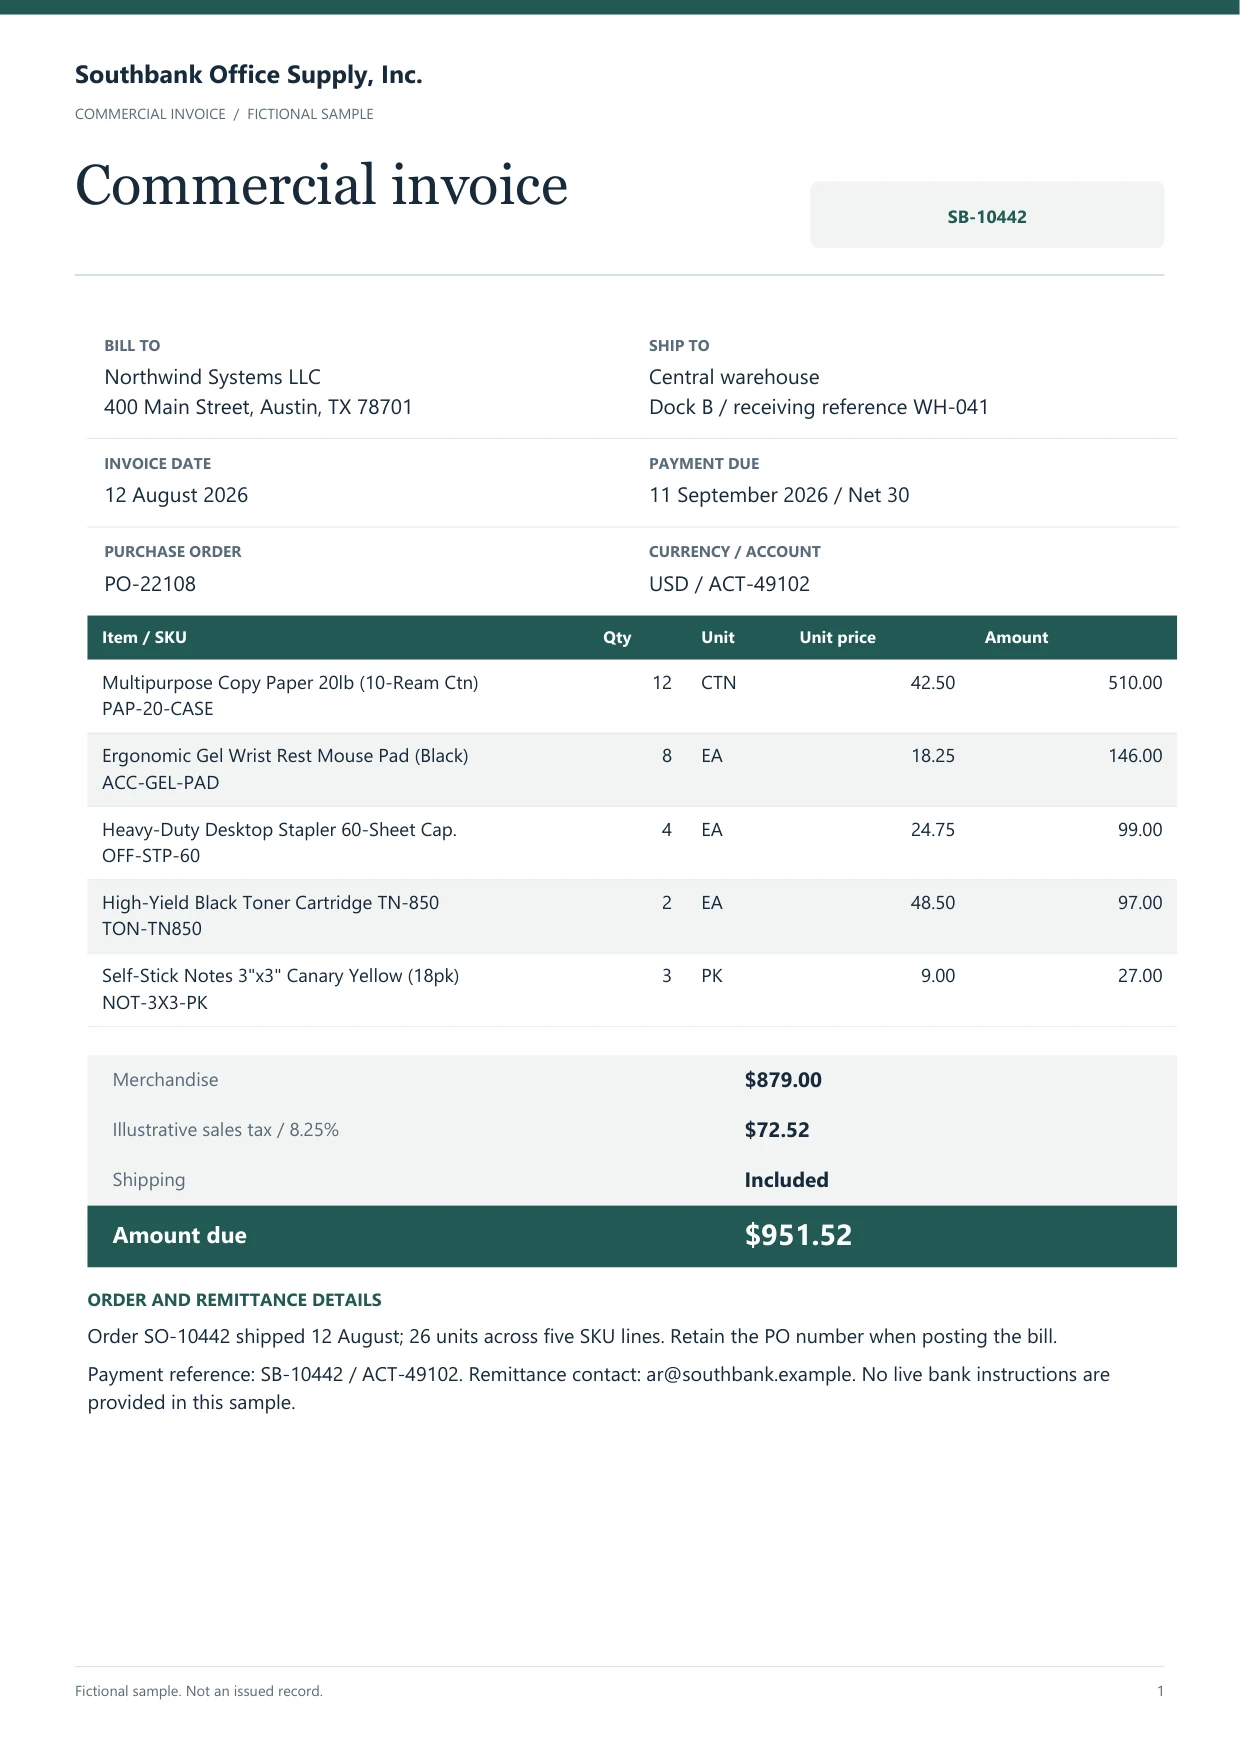
Office supply invoice · 1 page
Dynamite DocsParse native PDF text when it exists and reserve visual OCR for image-only or damaged regions.
Correct rotation and account for page size, crop boxes, embedded images, and repeated headers.
Group words into paragraphs, fields, tables, and sections instead of returning reading-order text alone.
Merge continued tables and repeated forms while keeping page references for review.
Structured output
Dynamite DocsA PDF can look correct in a viewer while its internal order is broken or its scan is too compressed to distinguish similar characters.
Implementation guide
Inspect the PDF before rasterizing it. Embedded text, fonts, page coordinates, and vector lines can provide cleaner evidence than a screenshot. Use direct parsing for reliable digital text, visual OCR for image-only pages, and a combined path when a file contains both. Password protection, malformed pages, unusual crop boxes, and rotated inserts should become explicit preflight errors instead of missing data.
Set the rendering resolution high enough for the smallest important text, but do not enlarge a blurred source and call it more accurate. Preserve color when stamps, highlights, or annotations carry meaning. For long files, record a result for every page, including blank, skipped, failed, and classified pages. A job marked complete should never hide an unreadable page in the middle of the packet.
Keep page coordinates with extracted fields and rows. They let a reviewer jump from a spreadsheet value to the exact source region and help diagnose reading-order errors. For tables that continue across pages, remove repeated headings only from the data output. Retain page references and row boundaries so the join can be checked.
Finish with file-level controls. Compare processed pages with the PDF page count, verify document sections, reconcile table row counts, and test totals or balances where the document provides them. Export unresolved values with a review state or null. A plausible guess is harder to find later than an honest exception.
Local PDF OCR with Ollama follows the same source checks. The local AI document extraction guide explains how the Windows companion uses embedded text for digital PDFs and image batches for scanned pages. Select a compatible vision model, check every processed page and review table joins before exporting structured JSON, Excel or CSV.
Send the original PDF when possible. Converting every page to a low-resolution screenshot throws away useful text and vector information.
Return page numbers, bounding regions, confidence, and a stable schema with extracted values. Keep raw OCR text available for diagnostics, not as the only output.
Make scanned records searchable while also capturing dates, identifiers, and tables.
Recover repeated rows from statements, schedules, and reports for review in Excel.
Send PDFs through one pipeline even when page types differ inside the file.
Free OCR tools
Upload one supported file and review the extraction before creating an account. Pick the tool that matches the document and output.
Try selecting and copying a sentence. If there is no text, the selection is incomplete, or the pasted order is scrambled, the page needs OCR or layout-aware parsing.
It can recover table structure, but merged cells, wrapped descriptions, borderless columns, and tables continued across pages still need explicit review.
Extraction should read the source and create a separate result. A searchable-PDF workflow may add a text layer to a copy, but it should not overwrite the original file.
Yes, with a compatible vision model and a workflow that renders the scanned pages for OCR. An Ollama PDF to text converter must preserve page order and distinguish transcription from structured data extraction. Dynamite Docs uses its [Windows companion](/local-ai-document-parser-on-windows) for local inference, then returns fields and rows for review and export.
Keep reading
Extract fields and tables from low-resolution or skewed scans with AI in Dynamite Docs. Check uncertain values and page order before exporting.
Read guideExtract borderless and multi-page tables with AI OCR in Dynamite Docs. Review columns, wrapped text, and continued rows before spreadsheet export.
Read guideExtract structured fields and tables from images with AI in Dynamite Docs. Review document photos, screenshots, and scans beside the source before export.
Read guideConnected Accounting & Document Automation
Can we save optional cookies?
Essential cookies keep you signed in. With your permission, optional analytics cookies and masked session replays help us understand usage and diagnose errors. Privacy policy. Change your choice anytime in Cookie settings.