Sections08
Reading time8 min
EvidenceProduct guide

Answer in 30 seconds

Turn a PDF into fields and tables you can inspect, correct and send somewhere useful.

A PDF may contain selectable text, scanned page images, positioned table cells, or all three. Dynamite Docs reads the text layer when it is available and uses the selected vision-capable model for image-only pages. It proposes named fields and table rows rather than returning only a text transcript.

Keep the PDF beside the result, check uncertain values, and fix rows that split across page boundaries before exporting to Excel, CSV, JSON, Google Sheets, or your API.

Upload a PDF in the browser. Create an account only when you want to save or export.
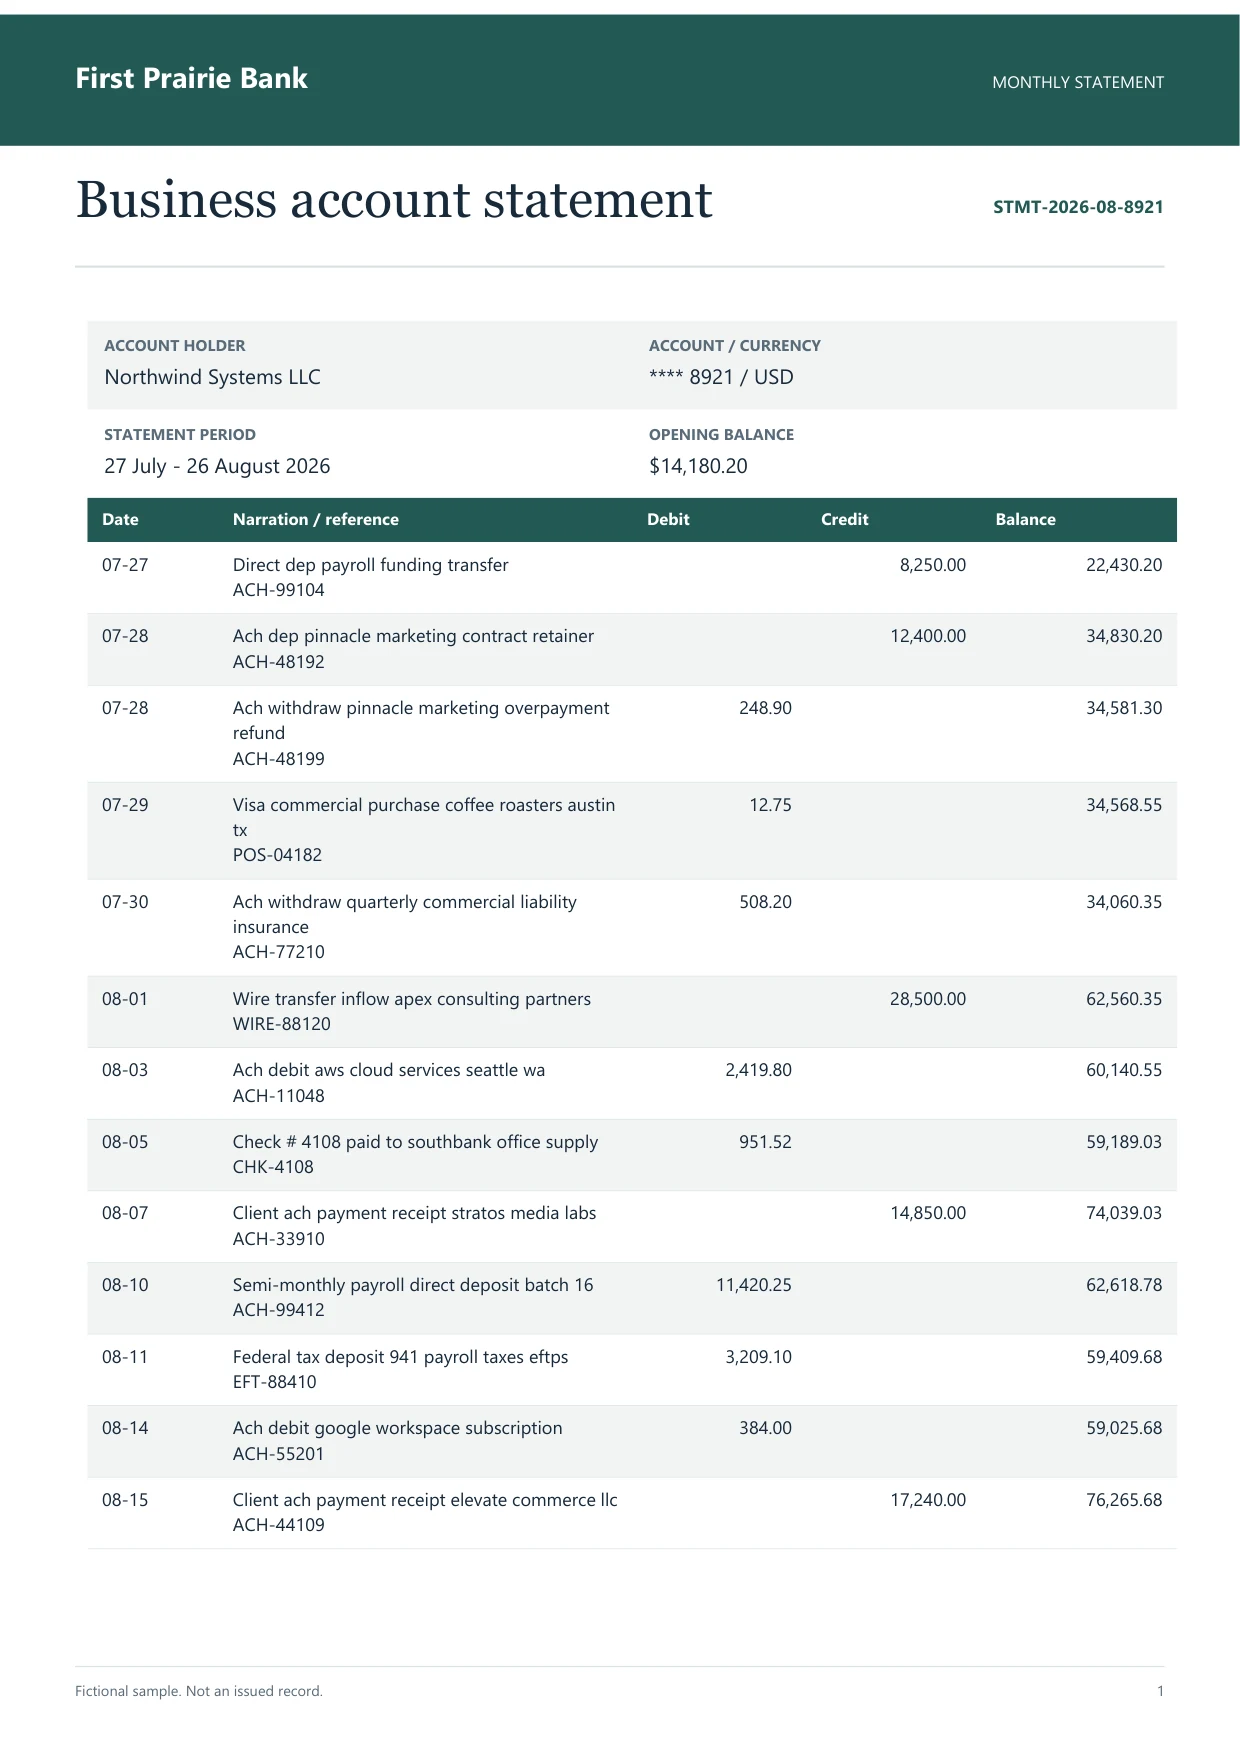
Check document extraction results with Dynamite Docs with these sample files

Input register

PDF inputs this workflow handles

01

Digital PDFs

Use the embedded text layer before calling a vision model.

02

Scanned PDFs

Read image-only pages with OCR and document layout.

03

Mixed PDFs

Handle native pages, scans and attachments in one file.

04

Multi-page tables

Join continued rows while checking repeated headers and totals.

Extraction schema

Fields and tables stay separate

The schema follows the document. Named values remain document fields, while repeating records become table rows.

Dynamite Docs logoDynamite Docs
Inside the output
Source table: Forms and tablesDocument fields: Report name, account, period, reference. Table headers: Date, description, quantity, amount. Repeating rows: One object per transaction or line item. Illustrative example, not extracted customer data.Forms and tablesfx Values from your documentAOutputBKeepsCBest used for12345ExcelSheets, tables and…Review and workbook…CSVOne flat table per…Imports and simple…JSONObjects, arrays and dat…APIs and automationDocument fields / RowsEditable cells,…
Document fields
Report name, account, period, reference
Table headers
Date, description, quantity, amount
Repeating rows
One object per transaction or line item
Keep form fields and table rows separate. Illustrative example.
Document fieldsReport name, account, period, reference
Table headersDate, description, quantity, amount
Repeating rowsOne object per transaction or line item
Dates and numbersNormalized values for sorting and calculation
Source contextOriginal page stays available during review
ConfidenceField and cell signals for focused checking

Procedure

From file to reviewed result

Dynamite Docs logoDynamite Docs
The handoff
Source table: Forms and tablesInspect the PDF. Propose fields and repeating rows. Review the source. Choose an output. Illustrative example, not extracted customer data.FROM SOURCE FILE TO A RESULT YOU CAN USESourcetableReview workspaceForms andtables1Inspect the PDF2Propose fieldsand repeatingrows3Review the source
  1. 01Inspect the PDF
  2. 02Propose fields and repeating rows
  3. 03Review the source
  4. 04Choose an output
Keep form fields and table rows separate. Illustrative example.
  1. 01

    Inspect the PDF

    Detect text, scanned pages, page count and layout before choosing the reading path.

  2. 02

    Propose fields and repeating rows

    The selected model identifies likely fields, table headers, and repeating rows without a coordinate template for every supplier layout.

  3. 03

    Review the source

    Compare uncertain cells with the original page and correct the result in place.

  4. 04

    Choose an output

    Download Excel, CSV or JSON, push to Sheets, or deliver reviewed data through the API.

Product evidence

See the source and extraction together using Dynamite Docs

The workspace keeps the PDF beside the extracted fields. Corrections stay in the table and can become reusable patterns for later files with the same layout.

A real product view of source-linked field review in Dynamite Docs.

Workflow Tour

8 steps

01 / Bring in files

Bring documents into one workspace.

Upload from your computer or choose files from Google Drive. Connected Dropbox and Slack workflows can bring in files too.

  • Google Drive logoGoogle Drive
  • Dropbox logoDropbox
  • Slack logoSlack
  • Local upload
Workspace preview01 / 08
Start with Import, then choose where your file comes from.
1 of 8
Worked Example: Document Input & Extracted Rows

One PDF, several useful outputs

The same reviewed result can feed a workbook, a flat file or a software integration. Choose the output after checking the structure.

Extract PDF Forms & Tables Using AI | Dynamite Docs: image OCR table extractionRead tables from an old scanned invoice without a template.
Extract PDF Forms & Tables Using AI | Dynamite Docs: OCR source view controlsSwitch views when an image needs closer OCR review.
Extract PDF Forms & Tables Using AI | Dynamite Docs: OCR text correctionCorrect OCR text while the original invoice stays visible.
Extract PDF Forms & Tables Using AI | Dynamite Docs: reviewed OCR line itemsCorrect image-derived line items before using the result.
OutputKeepsBest used for
ExcelSheets, tables and document fieldsReview and workbook handoff
CSVOne flat table per downloadImports and simple analysis
JSONObjects, arrays and data typesAPIs and automation
Google SheetsReviewed rows in a new tabShared operational work

Review gate

A clean table still needs a document check

Common Failure States & Troubleshooting

Encrypted files, damaged PDFs, missing pages and unreadable scans can fail before extraction. Unlock protected files and use the original scan where possible.

Confidence

Confidence signals narrow the review, but they do not prove a value is correct. Check identifiers, money, dates and required fields against the page.

Accuracy

Digital text avoids OCR character errors, yet reading order and table structure can still be ambiguous. Scans add blur, rotation, compression and handwriting risk.

Failure state

Encrypted files, damaged PDFs, missing pages and unreadable scans can fail before extraction. Unlock protected files and use the original scan where possible.

Product boundary

Dynamite Docs extracts and structures document data. It does not reproduce charts, decorative page layout or every merged cell as a visual copy.

Choose the processing path that fits the document using Dynamite Docs

Anonymous and Free files stay browser-only. Paid plans add cloud storage, with deletion and retention controls described in the product policies.

Every plan can connect provider keys. Free and Hobby runs use monthly PE; Pro and Ultra runs are unlimited. Hobby, Pro and Ultra can use the signed local Ollama companion for model inference on the user's computer.

Questions about pdf extraction software

Does PDF extraction work on scanned PDFs?

Yes. Image-only pages use OCR and visual document extraction. Clear, correctly oriented scans need less correction than compressed or skewed pages.

Is PDF extraction the same as copying PDF text?

No. Copying returns reading-order text. PDF extraction identifies named fields, tables, rows and data types that can move into a spreadsheet or API.

Can I extract more than one table from a PDF?

Yes. The result can contain several tables. Review their headers, page breaks and carried totals before combining or exporting them.

How to extract tables from multi-page PDFs without losing column headers?

Dynamite Docs joins continuous table rows across page boundaries, identifies repeated page headers, and reconciles carried subtotals into one clean table without duplicate header rows.

How does document extraction handle a new PDF layout?

The selected model reads labels, nearby values, table headers, and repeated row structure from the page. Review the first result carefully, then save confirmed corrections as a pattern for later files with the same layout.

Can we save optional cookies?

Essential cookies keep you signed in. With your permission, optional analytics cookies and masked session replays help us understand usage and diagnose errors. Privacy policy. Change your choice anytime in Cookie settings.